Luma Uni-1 · Text to Image
Generate images from a text prompt using Luma Uni-1, a reasoning-first image model that plans composition before rendering. Describe the scene, add optional reference images, and hit run.
image generation
luma uni-1
text to image
104
Nodes & Models
LumaUni1TextToImage_floyo
SaveImage
ABOUT THE WORKFLOW
Generate an Image from Text
Describe what you want and get an image back. Luma Uni-1 reasons through your instructions before rendering, so complex prompts with spatial layout, multiple subjects, or specific compositions land more reliably than with standard diffusion models. Add up to nine reference images to guide the output.
Partner node. This workflow calls an external API, so each run uses credits from your API wallet. No API key needed. Floyo handles the connection.
Model
Luma Uni-1 by Luma AI. An autoregressive reasoning model that plans composition, lighting, and spatial layout before generating. Strong at following detailed instructions and preserving reference images.
HOW IT WORKS
Step 1. Write your prompt
Describe the image you want. Subject, setting, lighting, style, camera angle. A sample prompt is pre-filled. Replace it or clear it and write your own.
Works great with: cinematic scenes · editorial photography · character art · product concepts
Step 2. Add reference images (optional)
Upload up to nine images to guide the output. Use them to lock in a subject, match a style, or set a composition. None are connected by default.
Step 3. Pick an aspect ratio
Choose 16:9, 1:1, 9:16, or another preset from the dropdown. No custom pixel dimensions.
Step 4. Hit run and download
The model reasons through the scene, generates the image, and returns it as a JPEG. Preview it in the workflow, then download.
Ready for: Photoshop · Figma · Canva · any editor
First time? Leave every setting as-is. The defaults (16:9 · auto style · web search off · JPEG) are the right starting point for almost everyone.
RECOMMENDED SETTINGS
Quick-start guide. Find the goal that matches yours and copy the settings.
Standard generation (most people) — 16:9 · auto style · web search off · JPEG. The right starting point for almost everyone.
Want a square or vertical image — Switch aspect ratio. 1:1 for social posts, 9:16 for vertical formats like stories or posters.
Want to match a specific subject or style — Upload one or more reference images. The model draws from them for subject, composition, or visual tone.
Generating a real-world location or landmark — Turn web search on so the model can look up how that place looks.
The layout is not matching your prompt — Add more spatial detail. This model reasons through placement, so "red car in the foreground, city skyline behind, low angle" lands better than "car in a city."
Output looks too stylized — Set style to auto and keep the prompt descriptive but plain. The model matches style to the prompt when left on auto.
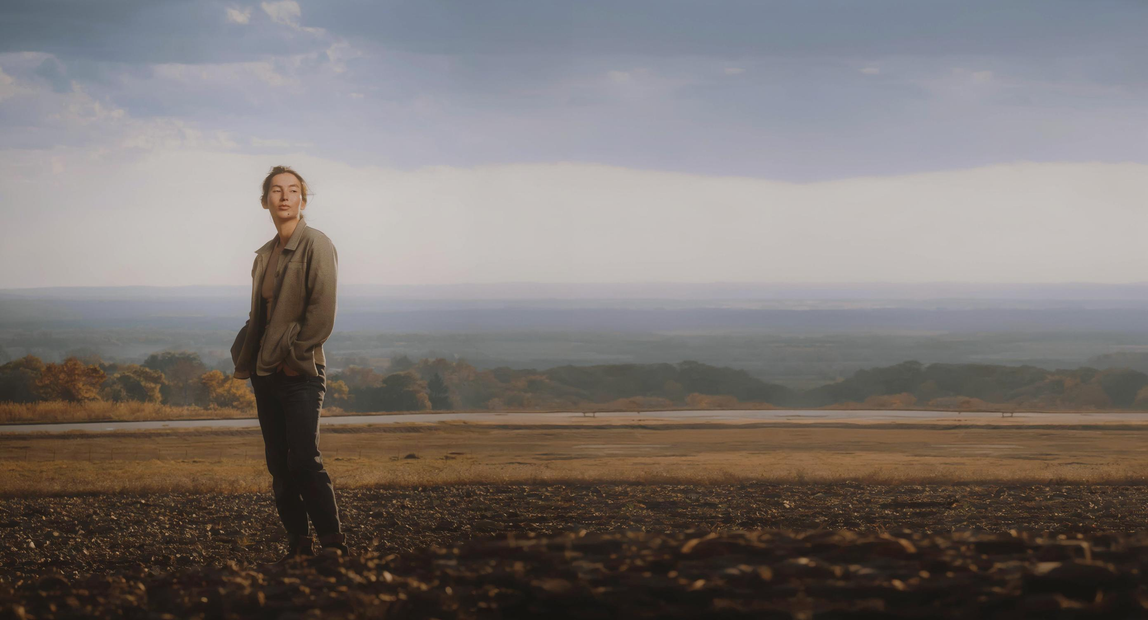
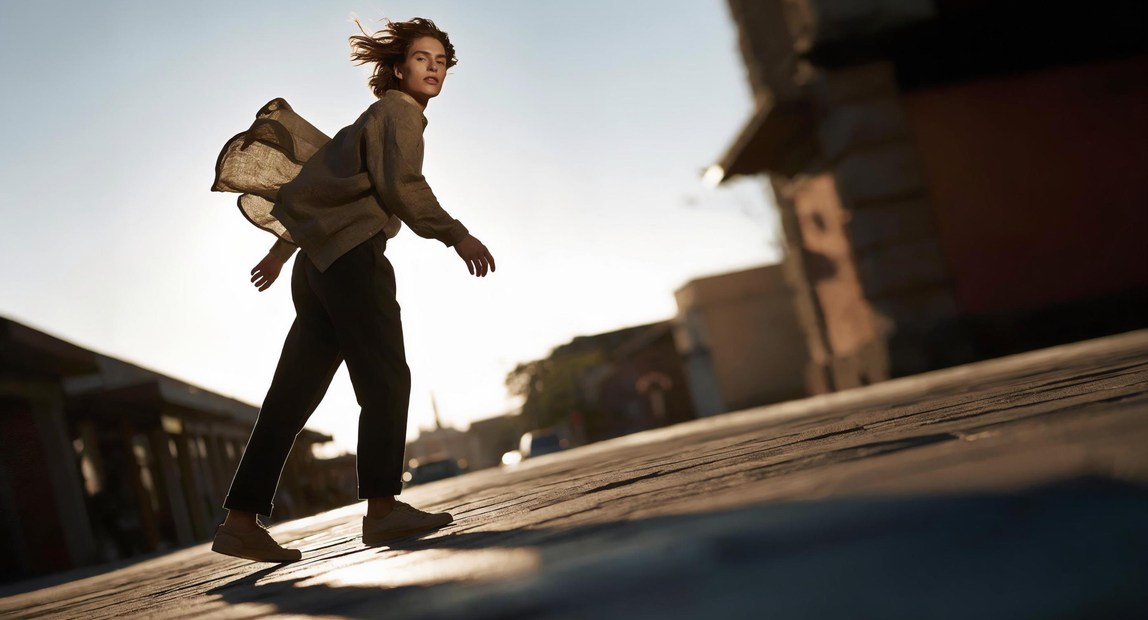
Prompt: Be specific about subject, setting, lighting, and camera. "A confident young woman walking through a sunlit Tokyo alley, low angle, shallow depth of field, warm afternoon light" works better than "woman in Japan." Uni-1 reasons through the scene before rendering, so extra detail helps rather than hurting.
LEARN
📹 Videos
ComfyUI 101 Free Course ft. Sebastian Kamph
Floyo 101 for Team Collaboration
✨ Quick links
USE CASES
🎬 Cinematic & Editorial
Generate scenes with specific camera angles, depth, and lighting direction. The reasoning step handles complex compositions that trip up diffusion models.
🧑🎨 Character Design
Upload a character reference and generate that subject in new poses, outfits, or environments. Uni-1 preserves features across generations more consistently than most models.
🖼️ Concept Art & Worldbuilding
Describe a scene with spatial relationships and the model plans the layout before rendering. Interiors, cityscapes, and environments with foreground-background depth work well.
📐 Reference-Guided Generation
Feed in style references, mood boards, or composition guides alongside the prompt. The model draws from them to shape the output without copying them.
WHAT WORKS BEST / WHAT TO AVOID
✅ Works great
Detailed prompts with subject, setting, lighting, and camera direction
Complex compositions with multiple elements in specific positions
Reference images for subject, style, or mood
Scenes that need spatial reasoning or logical layout
⚠️ May produce softer results
Very short, vague prompts like "a cool photo"
Prompts where raw photorealism matters more than composition
Too many reference images pulling in conflicting directions
Expecting custom pixel dimensions (aspect ratio presets only)
FAQ
What is Luma Uni-1?
Luma Uni-1 is a multimodal reasoning model by Luma AI, released in March 2026. It uses an autoregressive transformer architecture instead of diffusion, meaning it reasons through composition, lighting, and spatial layout before generating. It accepts a text prompt and up to nine reference images.
How is Luma Uni-1 different from diffusion models like Stable Diffusion or Flux?
Diffusion models start from random noise and progressively denoise it into an image. Uni-1 is an autoregressive transformer that processes text and image tokens in a single sequence, reasoning through the scene before rendering. The result is stronger instruction following, more accurate spatial layout, and better handling of complex multi-element prompts.
What are reference images and how do they work in Uni-1?
Reference images are optional uploads that guide the generation. You can use them to lock in a subject's appearance, match a visual style, or set a composition baseline. The model draws from them alongside your text prompt. Up to nine reference image slots are available in this workflow.
Is Luma Uni-1 good for photorealistic images?
Uni-1 produces high-quality images, but its strength is in following complex instructions and maintaining spatial logic. For simple prompts where raw photorealism is the only goal, models like GPT Image or Nano Banana may produce more immediately realistic results. For detailed scenes with specific compositions, Uni-1 often outperforms them.
Can I use Luma Uni-1 outputs commercially?
Luma Uni-1 is a proprietary closed-source model. Commercial use is generally permitted, but review Luma AI's current terms of service before using outputs in shipped products or client work.
Does Luma Uni-1 support transparent backgrounds?
This workflow outputs JPEG by default, which does not support transparency. Check the output format dropdown for other options. Transparent background support depends on the format and the API's current capabilities.
How to run Luma Uni-1 online?
You can run Luma Uni-1 online through Floyo. No installation, no setup, no API key to wire up. Open the workflow in your browser, write a prompt, and hit run. Free to try.
WHY FLOYO?
Floyo is the only platform with team collaboration for ComfyUI in the browser. You run workflows with no install. You share run history, assets, and models across your team. You pay only when you generate. Floyo supports open-source and closed-source models.
A designer runs an edit and likes the result. A teammate opens that exact run from shared history and keeps going. No file handoffs. No version confusion.
For studios and enterprise teams, Floyo adds private workspaces, pooled resources, and a team usage dashboard. Other ComfyUI cloud tools run for one person at a time. Floyo runs for the whole team, with transparent per-generation costs.
Ready to try it?
Write a prompt, pick an aspect ratio, and run it. A sample prompt is already set.
Questions? Watch the free course or check the FAQ above.
Read more