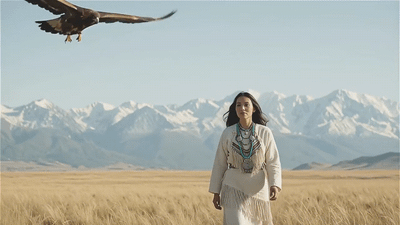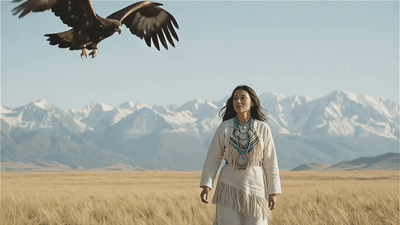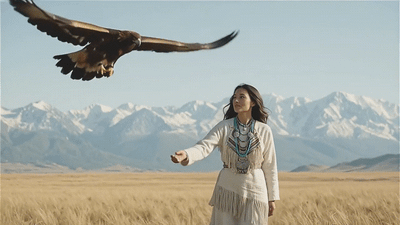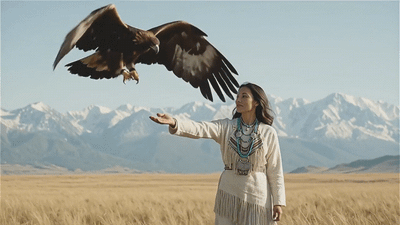
LTX-2.5 · First and Last Frame to Video
Set a start image and an end image. LTX-2.5, Lightricks' open-source 22B video model, fills in the motion and audio between them. Upload two frames and hit run.
first frame and last frame
image to video
ltx-2.5
video generation
114
Nodes & Models
LoadImage
ManualSigmas
SamplerEulerAncestral
LTXVPreprocess
RandomNoise
LTXVEmptyLatentAudio
PrimitiveInt
LTXVCropGuides
SaveVideo
EmptyLTXVLatentVideo
LTXVConditioning
GetImageSize
LTXVAddGuide
LTXVConcatAVLatent
SamplerCustomAdvanced
ComfyMathExpression
ResizeImageMaskNode
CLIPTextEncode
CreateVideo
VAEDecodeTiled
LTXVAudioVAEDecode
LTXVSeparateAVLatent
VAELoader
ltx-2.5-audio-vae-bf16.safetensors
ltx-2.5-video-vae-bf16.safetensors
CLIPLoader
gemma4-12b-with-proj-ltx-2.5-bf16.safetensors
gemma4_e2b_it_bf16.safetensors
UNETLoader
ltx-2.5-22b-distilled-transformer-bf16.safetensors
LTXVDualCFGGuider
ComfySwitchNode
PreviewAny
PrimitiveBoolean
PrimitiveStringMultiline
ABOUT THE WORKFLOW
Build a video between two images
Upload a start frame and an end frame. The model figures out what happens in between: the motion, the camera move, the transitions, and the sound. You get back one video file with synced audio, ready to drop into an edit.
Model
LTX-2.5 by Lightricks. A 22B open-source video model released in August 2026 that generates video and audio in a single pass. Strong at first-and-last-frame transitions, synced audio, and holding identity across a clip.
HOW IT WORKS
Step 1. Upload your first frame
The image the video opens on. It sets the subject, scene, and starting look for the clip.
Works great with: renders · photos · concept art · stills from existing footage
Step 2. Upload your last frame
The image the video ends on. For smooth motion, match the subject, lighting, and framing of the first frame. The bigger the visual gap between the two, the more creative liberty the model takes to bridge them.
Step 3. Write a prompt (optional)
Describe the motion, camera move, and sound between the two frames. Example: "The hand rotates slowly at the wrist, joints glowing, a low electrical hum fills the space." Prompt enhance is on by default and expands a short prompt before generating, so a few clear sentences are enough.
Step 4. Hit run and download
The model generates the video and audio together in one pass. The finished file saves under video/ltx2.5_flf2v.
Ready for: Premiere · After Effects · DaVinci Resolve · Blender
First time? Leave every setting as-is. The defaults (1280 x 720 · 5 seconds · 24 fps · prompt enhance on) are the right starting point for almost everyone.
RECOMMENDED SETTINGS
Quick-start guide. Find the goal that matches yours and copy the settings.
Standard generation (most people) — 1280 x 720 · 5 seconds · 24 fps · prompt enhance on · random seed. The right starting point for almost everyone.
Need a shorter transition? — Drop the duration below 5 seconds. Shorter clips keep the motion tighter and generate faster.
Need a longer clip? — Raise the duration. The model handles longer clips, but raising resolution and duration together increases generation time more than raising either on its own.
Want more control over what the model writes? — Turn prompt enhance off. When it is on, the model expands your text before generating. Off gives you exact control over what goes in, but you need to write a more detailed prompt yourself.
The motion is wrong or unexpected — Describe the movement more specifically in the prompt. Name the direction, speed, and camera behaviour. Vague prompts let the model guess, and the guess may not match what you picture.
The transition looks jumpy or inconsistent — Match the subject, lighting, and framing between your two frames more closely. The model fills in the gap, and a large visual mismatch forces it to invent more of the in-between.
Want to reproduce a result? — Lock the seed to a fixed number. Same seed plus same inputs returns the same clip, so you can change one setting at a time and compare.
Prompt: Describe what happens between the frames, not what the frames look like. The images handle appearance. The prompt handles motion and sound. "The camera pushes in slowly, fabric ripples in the wind, a soft ambient hum builds" is specific. "A cool video" gives the model nothing to work with.
LEARN
📹 Videos
ComfyUI 101 Free Course ft. Sebastian Kamph
Floyo 101 for Team Collaboration
✨ Quick links
USE CASES
🎬 Scene Transitions
Set frame A and frame B from two shots in your edit. The model builds the in-between, camera move and all, giving you a generated transition instead of a hard cut or a cross dissolve.
🎨 Concept Art to Motion
Take two concept art stills from a sequence and generate the movement between them. Useful for pitching how a scene reads in motion before committing to a full animation pass.
📱 Social and Short-Form Content
Drop a before-and-after pair and get a reveal clip with synced sound, ready for a product launch post, a tutorial transition, or a reel hook.
🎮 Game Cinematics and Previs
Feed rendered stills from a game engine as first and last frames to generate connecting footage for trailers, cutscene drafts, or pitch decks.
🔊 Audio-Synced Clips
The model generates video and audio together, so the sound matches what is happening on screen. Useful when you need a clip with ambient audio, impacts, or atmospheric tone and do not want to score it separately.
WHAT WORKS BEST / WHAT TO AVOID
✅ Works great
First and last frames with matched subject, lighting, and framing
Clear, specific motion prompts naming direction and speed
Moderate visual gaps the model can bridge naturally
720p at 5 seconds as the starting point
⚠️ May produce softer results
Large visual mismatches between the two frames
Very long durations at high resolution in one pass
Vague or empty prompts that leave all motion decisions to the model
Width or height values that are not multiples of 32
FAQ
What is LTX-2.5?
LTX-2.5 is an open-source video generation model from Lightricks, released in August 2026. It has 22B parameters and generates video and audio together in one pass. It supports text, image, and video inputs, and outputs up to 4K HDR at 24 fps. It is licensed under Apache 2.0 with weights on Hugging Face.
Does LTX-2.5 generate audio too?
Yes. Video and audio are generated jointly in a single pass, not stitched together afterwards. The sound is synced to what is happening on screen, so you get ambient tone, impacts, and atmospheric audio without a separate scoring step. If you do not want the audio, strip it in your editor after download.
What is prompt enhance and should I leave it on?
Prompt enhance is on by default. It expands your short prompt into a longer, more detailed version before the model generates. For most people it produces better results from less writing. Turn it off when you need exact control over every word in the prompt and do not want the model rewriting it.
Do the first and last frames need to match exactly?
They do not need to be identical, but they should share the same subject, similar lighting, and comparable framing. The model fills in the motion between them, and a large visual gap forces it to invent more of the in-between, which increases the chance of artifacts or unexpected transitions.
What resolution and duration should I use?
Start at 1280 x 720 and 5 seconds. That is the tested default and generates in a reasonable time. Raising resolution and duration together is harder on the model than raising either alone, so step up one at a time. Width and height must be multiples of 32 or the run fails.
Is LTX-2.5 open source and can I use the output commercially?
Yes to both. LTX-2.5 is released under the Apache 2.0 license, which permits commercial use, modification, and redistribution. Outputs you generate carry full commercial rights, provided you hold the rights to any images you upload.
How is this different from a standard image-to-video workflow?
A standard image-to-video workflow takes one image and a prompt, and the model decides where the clip ends up. This workflow anchors both the start and the end, so the model only fills in the motion between two known frames. That gives you far more control over what the transition looks like and where it lands.
How to run LTX-2.5 online?
You can run LTX-2.5 online through Floyo. No installation, no setup, no API key to wire up. Open the workflow in your browser, upload your inputs, and hit run. Free to try.
WHY FLOYO?
Floyo is the only platform with team collaboration for ComfyUI in the browser. You run workflows with no install. You share run history, assets, and models across your team. You pay only when you generate. Floyo supports open-source and closed-source models.
A designer runs an edit and likes the result. A teammate opens that exact run from shared history and keeps going. No file handoffs. No version confusion.
For studios and enterprise teams, Floyo adds private workspaces, pooled resources, and a team usage dashboard. Other ComfyUI cloud tools run for one person at a time. Floyo runs for the whole team, with transparent per-generation costs.
Ready to try it?
Upload a first frame and a last frame, then run it. The settings are already set.
Questions? Watch the free course or check the FAQ above.
Read more