LTX-2.3-MSR_V2_Sample_workflow
Welcome to LTX 2.3 MSR V2 (Multiple Subject Reference)
Audio
LTX
Video
356
Nodes & Models
GetNode
LTXAVTextEncoderLoader
gemma_3_12B_it.safetensors
Ver Private
Comm Use
ltx-2.3-22b-distilled-1.1.safetensors
LTXVAudioVAELoader
LTX23_audio_vae.safetensors
ManualSigmas
KSamplerSelect
RandomNoise
INTConstant
LowVRAMCheckpointLoader
ltx-2.3-22b-distilled-1.1.safetensors
LoadImage
SetNode
ComfyMathExpression
EmptyLTXVLatentVideo
LTXVEmptyLatentAudio
CLIPTextEncode
PromptRelayEncode
LTXAddVideoICLoRAGuide
LTXICLoRALoaderModelOnly
LTX-2.3-Licon-MSR-V2.safetensors
LTXVConditioning
LTX2_NAG
LTXVConcatAVLatent
CFGGuider
SamplerCustomAdvanced
LTXVSeparateAVLatent
LTXVCropGuides
LTXVAudioVAEDecode
VAEDecode
LiconMSR
VHS_VideoCombine
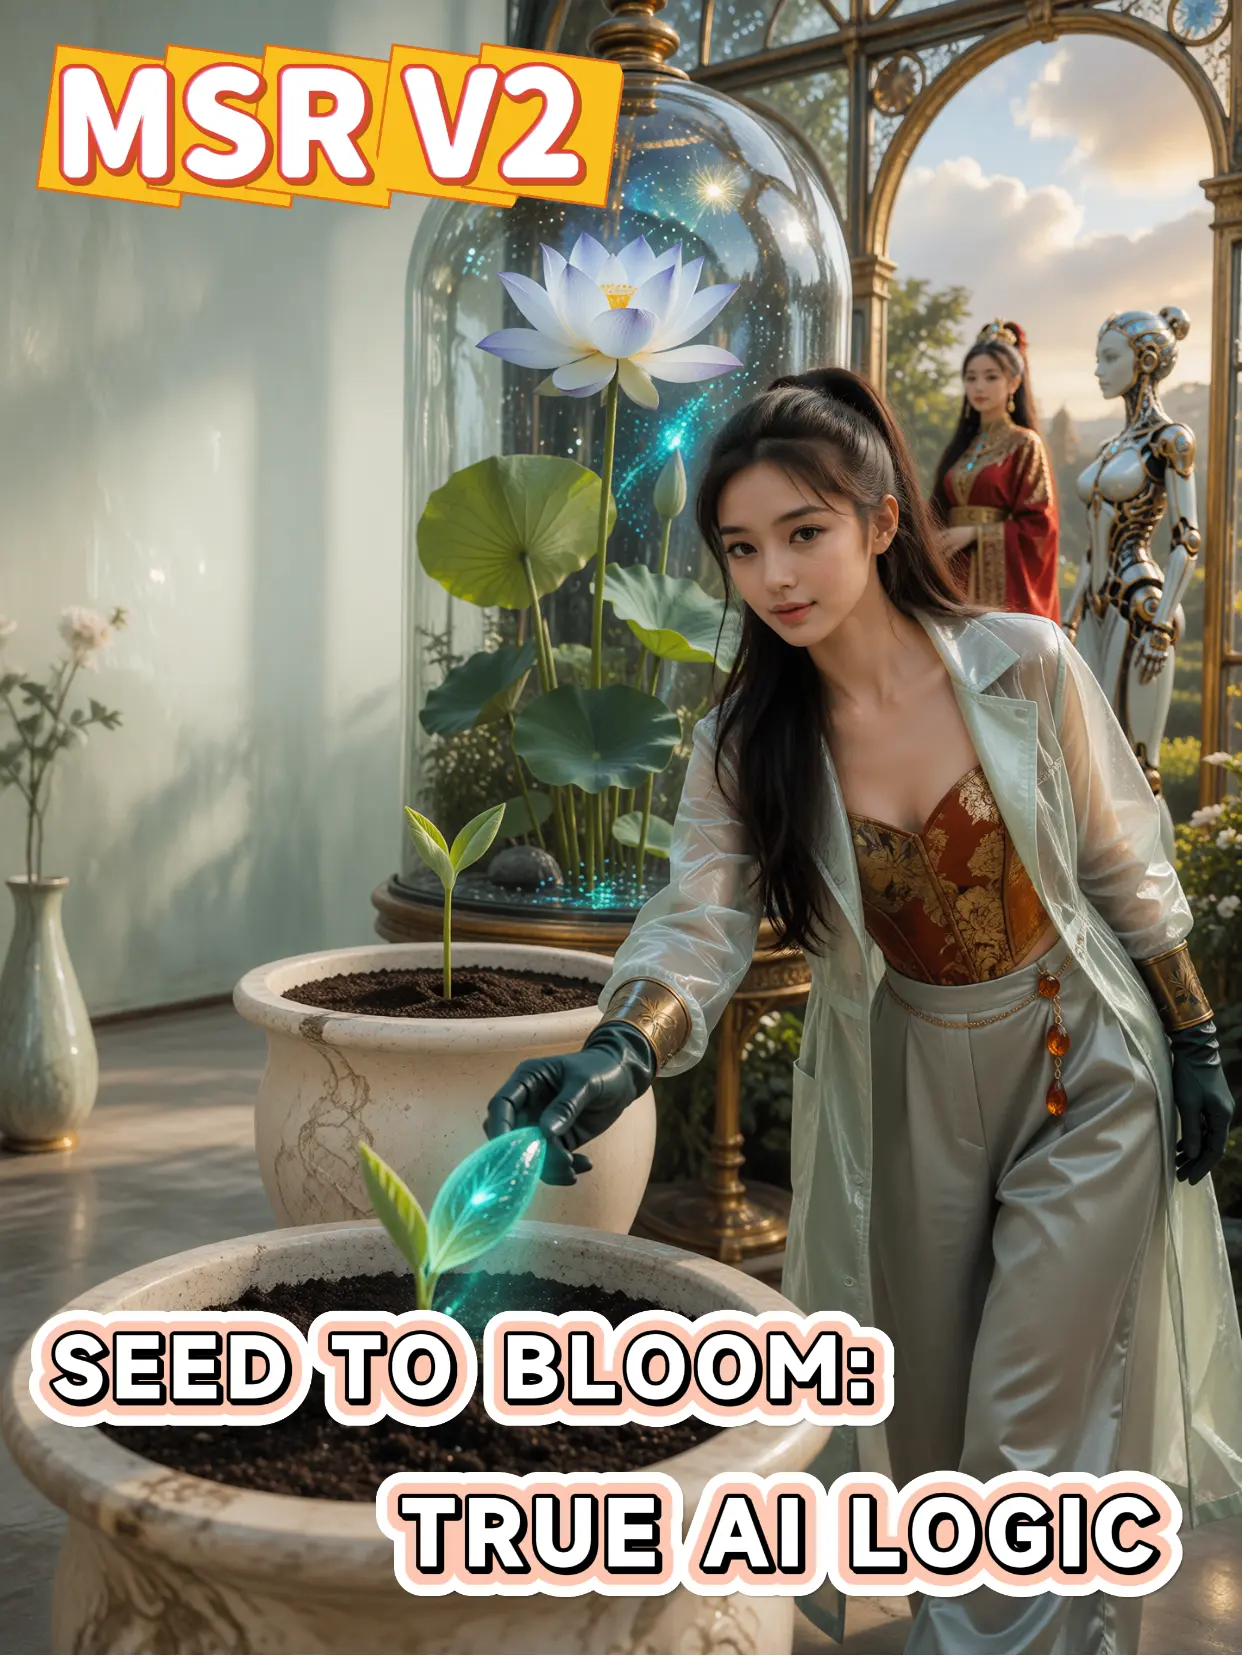
Can AI video move beyond simple "Image-to-Video" and start telling logical stories? 🎬 Welcome to LTX 2.3 MSR V2 (Multiple Subject Reference)! This isn't just an incremental update; it's a revolutionary way to organize your AI assets into a coherent event.
In this tutorial, I’ll show you how to use the LiconMSR node to package characters, props, and backgrounds into a "Visual Memory" sequence. We’ll test the limits of its "Event Logic" (from seed to bloom) and see how it performs in complex Multi-Shot scenarios where character identity usually fails.
Read more
N